Continue with Google
Boundary Detection
Finds where a table begins and ends, even when text sits above and below it.
Totals, line items, and schedules sit inside tables, and a table copied out of a file usually arrives as a jumble of text. ExtractMails performs table extraction from documents by finding each grid, keeping its rows and columns intact, and returning the cells in order.
Before table extraction from documents can return clean rows, ExtractMails must decide where a table starts, where it ends, and which cells belong together.
Finds where a table begins and ends, even when text sits above and below it.
Keeps each value under its own heading, including columns with no ruled lines.
Treats the top row as column names and carries them into every record.
A heading spanning several columns is applied to each column it covers.
Rows marked Subtotal or Total can be kept, labeled, or left out.
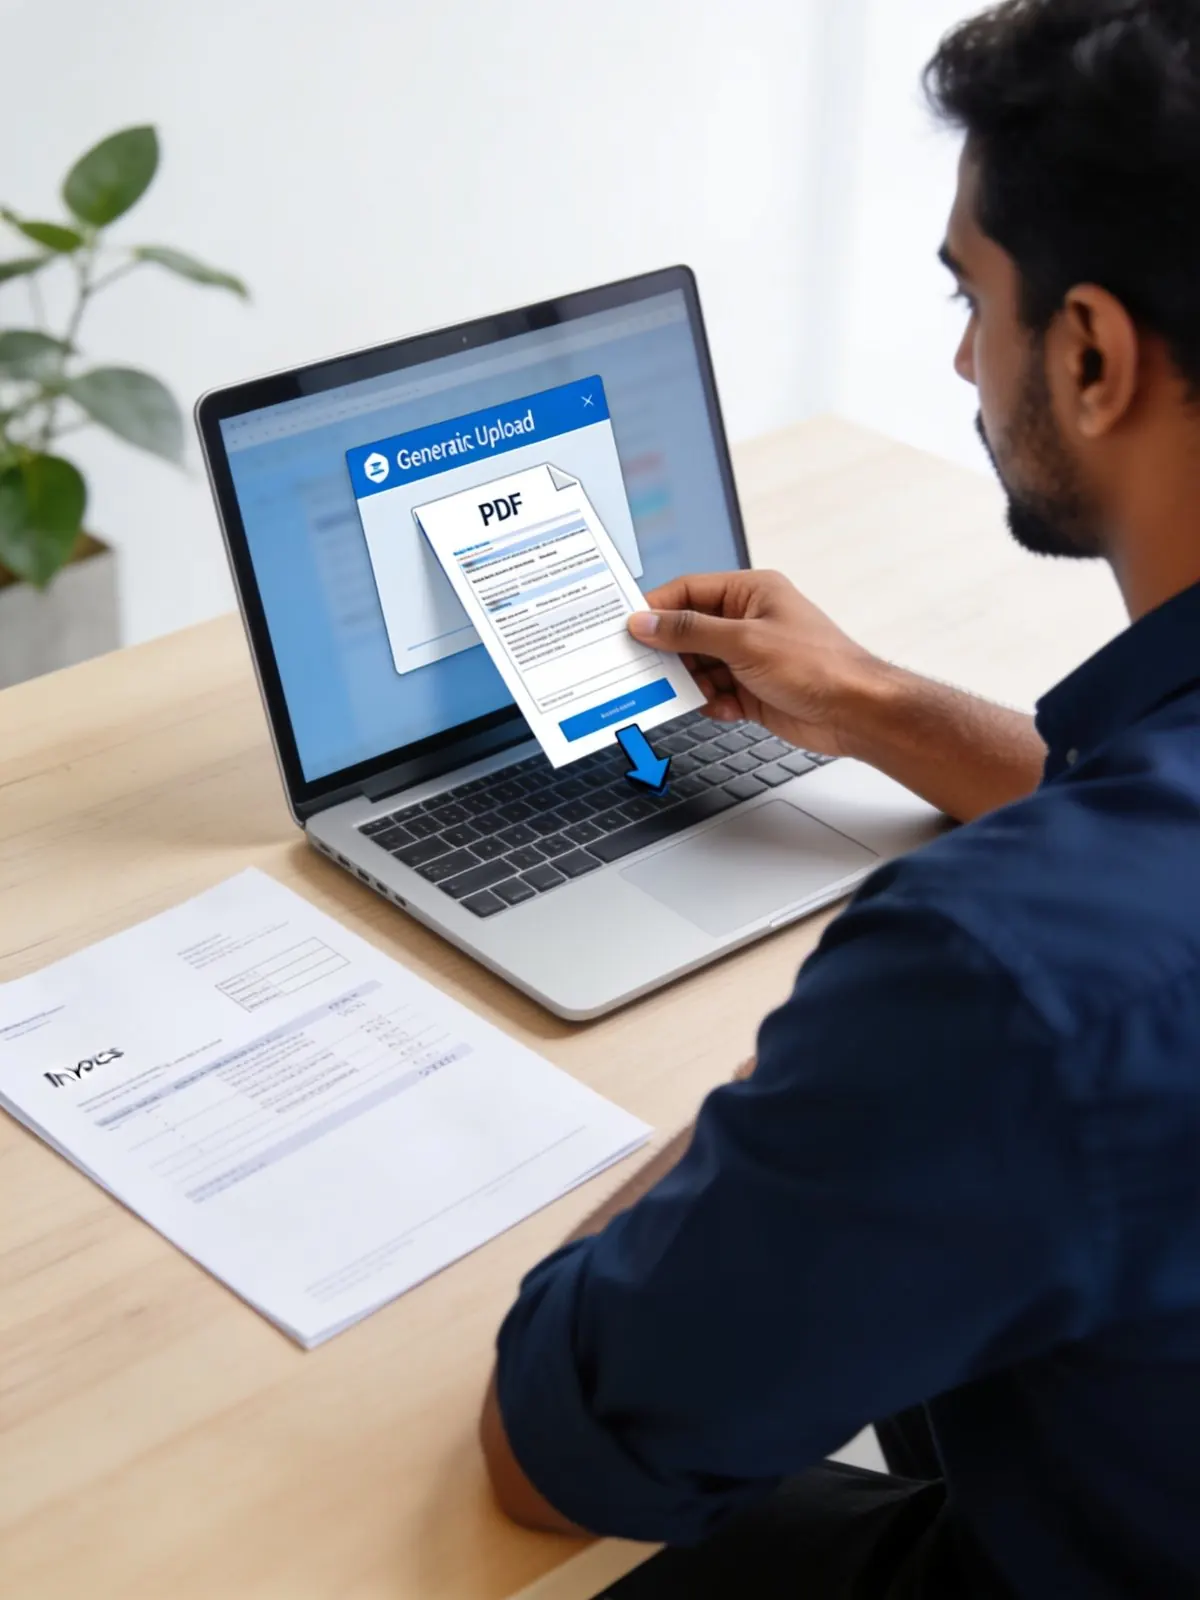
Running table extraction from documents on a regular basis comes down to one setup that later files reuse.
Upload a file or forward an email with the document attached.
Draw a box around the table or name the heading above it.
Confirm column names and mark the ones you want returned.
Download the cells as a spreadsheet or send them to another system.
A tool built for table extraction from documents should recognize ruled grids, borderless columns, and tables that run across pages.
Cells outlined by lines are read cell by cell.
Tables held together only by spacing are split by where the text aligns.
A table that continues on the next page is joined, and repeated headings are dropped.
Two-level headings, such as Quarter above Month, become one column name.
A small table nested in a cell is returned as its own list.
A shifted column can quietly corrupt a whole sheet, so ExtractMails gives you ways to catch it before the cells leave.
Rows with more or fewer cells than the header are marked.
Added-up line items are compared with the printed total.
Select a cell to see the part of the page it was read from.
Values the reader is unsure about are highlighted for review.
Teams use table extraction from documents wherever figures are stuck in a layout that a spreadsheet cannot read.
Capture item, quantity, rate, and amount for every row.
Return date, description, debit, and credit as separate columns.
Read product codes and prices from supplier catalogs.
Collect consignment numbers, weights, and destinations from cargo lists.
Pull period-by-period figures from statements and annual reports.
Read result tables with units and reference ranges.
Reliable table extraction from documents saves the hours people spend straightening pasted text in a spreadsheet.
Pasted tables rarely line up, and here they arrive already in columns.
Every record carries its column names, even across page breaks.
Statements from the same bank reuse the saved outline.
Each value can be checked against its place on the page.
It locates tables inside files, reads each cell, and returns the rows and columns as structured data instead of loose text.
Yes, where the text lines up in clear columns. Results depend on file quality.
Pages are joined into one table, and repeated headings are removed so the rows stay continuous.
Yes. Name the columns you need, and the rest are left out.
Check the marked cells beside the source page before export.
To a spreadsheet download or supported systems through webhooks and APIs, depending on your setup.
Supported file types depend on your setup. Confirm yours during onboarding.
Bring ExtractMails into your workflow for table extraction from documents. Upload one file with a difficult table, name the columns you need, and compare each row with the page.