Continue with Google
Field Capture
Choose the values you need, such as invoice number, due date, or total, and get them back under those names.
Many business details sit inside PDFs where they cannot be sorted or searched by field. ExtractMails lets your team extract data from PDF files, such as invoice totals and order numbers, and receive each value in its own labeled field.
ExtractMails handles reading, field matching, and checking, so nobody scrolls through pages hunting for numbers.
Choose the values you need, such as invoice number, due date, or total, and get them back under those names.
Pull line items, quantities, and prices from tables that run across many rows.
Process statements and reports that spread one record over several pages.
Save your field setup for a layout so later files from the same sender follow it.
Compare extracted values against the page before anything is sent out.
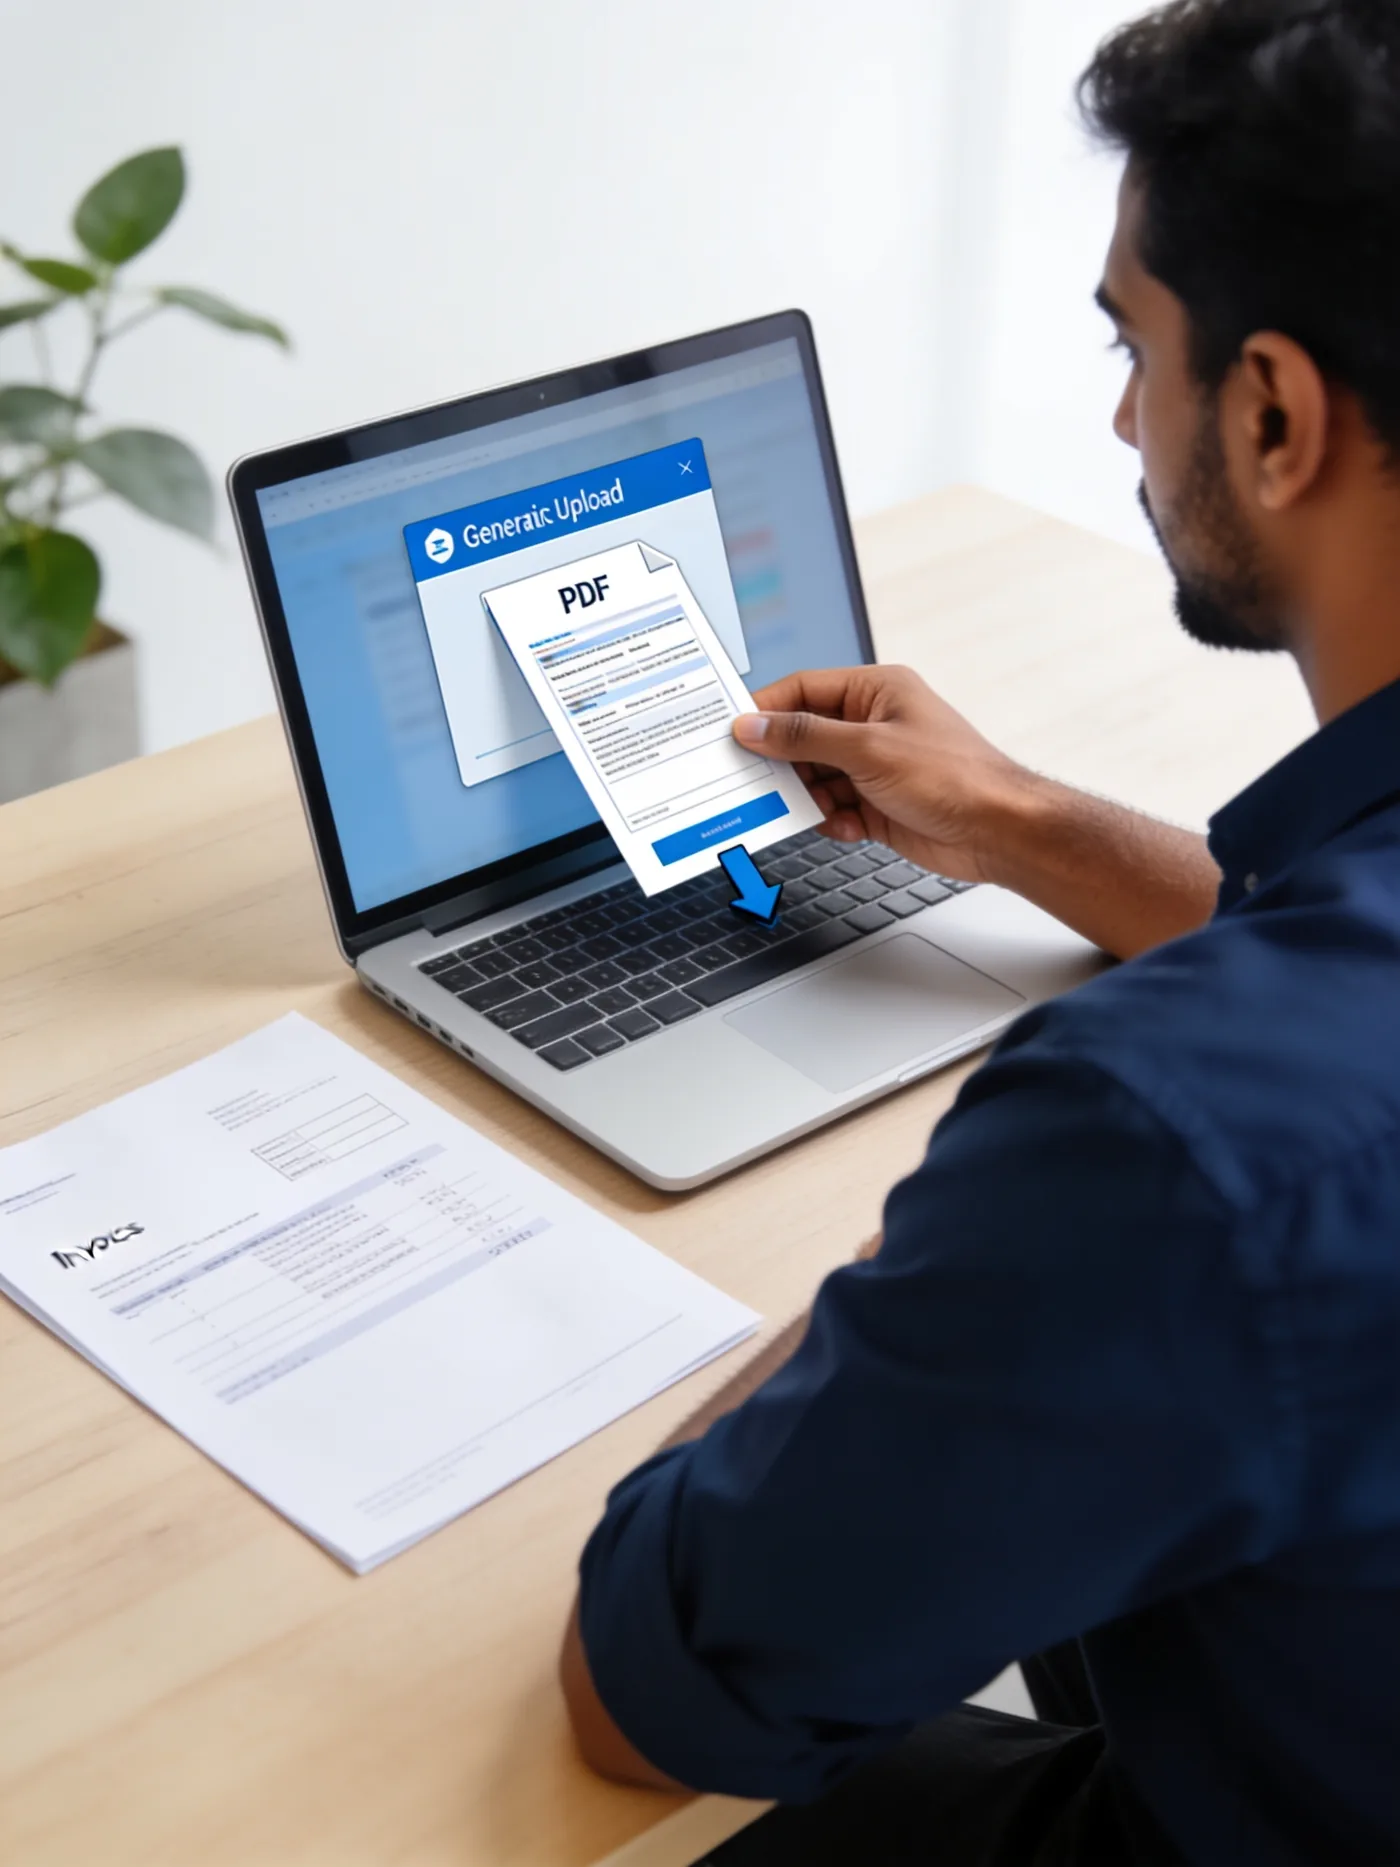
If you need to extract data from PDF files on a regular basis, the setup is short and done only once.
Upload a file or forward an email with the PDF attached.
Point to the values you want, such as vendor name, date, or order total.
Review each value beside the original page and correct anything that is off.
Export the data to your spreadsheet, CRM, or other system.
Business PDFs rarely look alike, so a PDF parser has to handle more than one-page designs.
Order forms and receipts with labeled boxes and short answers.
Statements and summaries with figures spread over several pages.
Invoices and packing lists where each row holds an item, quantity, and price.
One PDF holding many invoices or entries, split into separate records.
Once values are pulled out, they should arrive in a format your team can use at once.
Each file becomes a row, with one column for every field.
Add contact and deal details to a supported CRM.
Store values with the field names already attached.
Post the data to your own application when processing ends.
Any team that opens a PDF only to copy numbers elsewhere can hand that job to a PDF parser.
Read vendor invoices and capture totals, dates, and payment terms.
Collect order details from supplier quotes and purchase orders.
Pull contact and requirement details from forms and proposals.
Capture shipment and tracking details from delivery paperwork.
Note dates, parties, and reference numbers from contracts and filings.
Speed counts, but so does knowing each value came from the right spot on the page.
Stop keying numbers from the screen into another system.
Files with one layout return values under the same labels.
See each value next to the page it came from.
A single file or a full batch follows the same setup.
Begin with the PDF type your team handles most, then add others.
A tool that opens a PDF, finds the values you choose, and returns them as separate fields instead of one block of text.
Yes. Table rows can be read as line items where the file layout supports it.
Support for scanned pages depends on your setup. Confirm this process while onboarding.
No. Fields you define can be reused for PDFs that share a layout.
Yes. You can review each value and fix it before it leaves ExtractMails.
To supported spreadsheets, CRMs, databases, and custom systems through webhooks and APIs.
No. Accounting, procurement, sales, logistics, and legal teams can all use it.
Add ExtractMails to your workflow as the PDF parser that turns pages into usable fields. Upload one file, choose the values you need, and compare the result with the original.